Imagine handing your computer a complex project and walking away for coffee. When you return, the work is done, tested, and deployed. That’s the promise of high-level LLM agent autonomy. But right now, most of us are stuck in a different reality: we’re micromanaging AI, correcting its mistakes line by line, and wondering when it will actually become useful on its own.
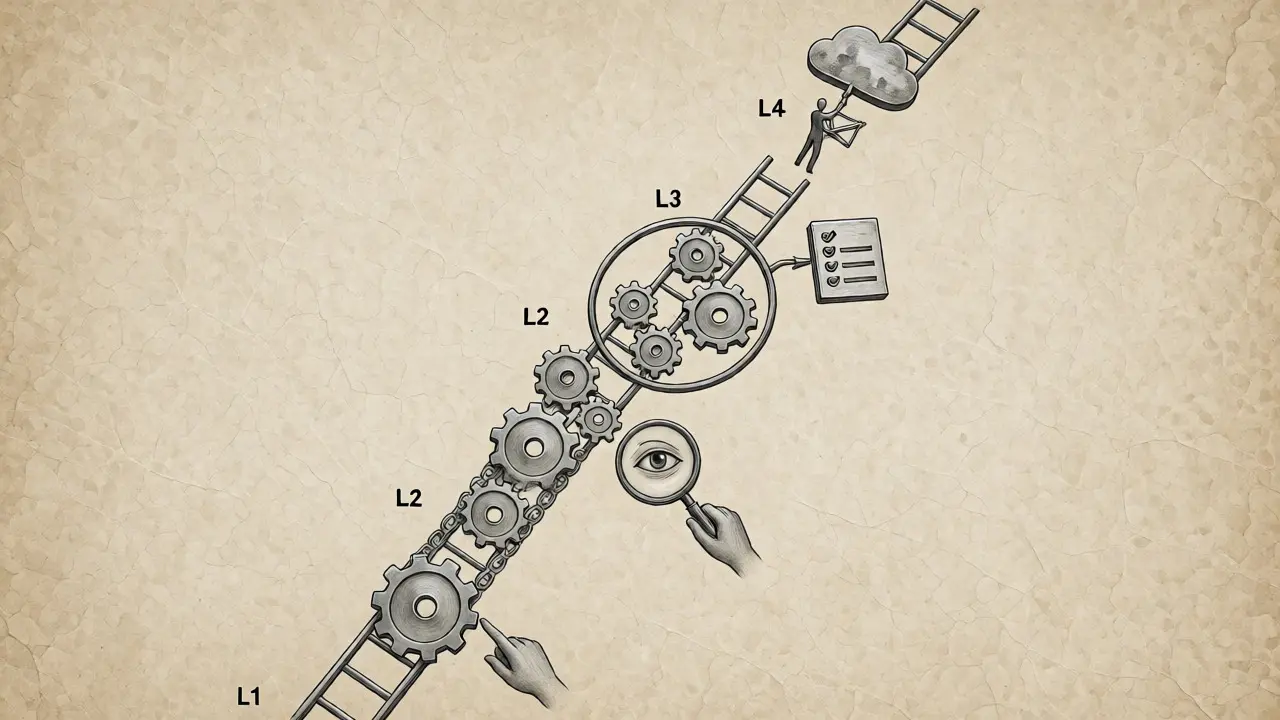
The confusion often stems from treating all AI tools as if they have the same capabilities. They don’t. There is a spectrum of independence, ranging from simple chatbots that wait for your every command to sophisticated systems that plan, execute, and self-correct without you breathing down their necks. Understanding where your current tools sit on this spectrum-and where you want them to be-is crucial for building efficient workflows in 2026.
Why We Need an Autonomy Framework
Before we get into the specific levels, let’s talk about why this distinction matters. In traditional software development or data analysis, humans make almost every decision. The code does exactly what you tell it to do. If you forget a semicolon, it breaks. If you want it to sort a list, you write the sorting logic.
Large Language Model (LLM) agents change this dynamic by introducing probabilistic reasoning and iterative planning capabilities. Unlike standard scripts, these agents can interpret vague instructions, break them down into steps, and attempt to solve problems they haven’t seen before. However, giving them too much freedom too quickly leads to chaos. Giving them too little renders them useless overhead. The L1 to L4 framework provides a clear mental model for balancing control and efficiency.
The Core Trade-Off: Control vs. Scale
Every step up the autonomy ladder shifts responsibility. At lower levels, you are the architect and the builder. At higher levels, you become the product manager, defining goals while the agent handles execution. This shift isn’t just technical; it’s psychological and operational. It changes how you structure teams, how you write specifications, and how you handle errors.
Level 1: The Reactive Assistant (User as Operator)
Let’s start with where most people are today. Level 1 (L1) autonomy is what you experience when you use standard chat interfaces like ChatGPT, Claude, or basic GitHub Copilot completions. Here, the user is the operator. The AI is a passive tool waiting for input.
Think of L1 agents as highly skilled interns who only act when you explicitly tell them what to do, step by step. They don’t remember previous conversations unless you paste the context back in. They don’t check if their previous action worked. They don’t decide to run a test because they feel like it. If you ask them to write a function, they write it. If that function has a bug, they won’t notice until you point it out.
| Attribute | Description |
|---|---|
| Control Loop | None. One-shot interaction. |
| Memory | Session-based only; no persistent state across tasks. |
| Action Execution | Generates text/code; user must manually apply/run it. |
| Error Handling | User identifies errors and prompts for fixes. |
| Best For | Brainstorming, quick snippets, explanations, learning. |
The biggest limitation here is the lack of agency. An L1 agent cannot "think" about whether its output is correct relative to the broader goal. It doesn’t know if the code it just wrote fits into the existing architecture. You are doing 90% of the cognitive heavy lifting. The agent is just a fancy autocomplete engine.
However, L1 is invaluable for low-stakes tasks. If you need to generate a regex pattern or summarize a paragraph, the overhead of setting up an autonomous agent isn’t worth it. It’s fast, predictable, and safe because you retain full accountability for every character generated.
Level 2: Partial Automation with Human Oversight
Level 2 introduces the concept of delegation. At Level 2 (L2) autonomy, the agent can perform multi-step tasks but still requires human approval at critical checkpoints. This is the "co-pilot" mode taken seriously.
In this scenario, you might ask an agent to "refactor this module." Instead of just spitting out new code, the agent analyzes the file, proposes a plan, and then executes the changes. Crucially, it pauses after each significant step-like deleting a dependency or changing a function signature-to ask, "Is this okay?" You review the diff, click approve, and it moves to the next step.
L2 agents begin to exhibit short-term memory within a task. They track progress through a checklist. If a step fails, they might retry once before asking for help. This level reduces the number of interactions required but keeps you firmly in the driver’s seat. It’s ideal for medium-complexity tasks where you trust the agent’s capability but not its judgment. For example, updating library versions or formatting large blocks of code.
The risk at L2 is complacency. Users often start approving changes without reading them, assuming the agent knows best. This can lead to subtle bugs that propagate downstream. To mitigate this, effective L2 systems provide clear summaries of changes and highlight potential risks, forcing you to engage rather than just rubber-stamp.
Level 3: Conditional Autonomy in Defined Scope
This is where things get interesting. Level 3 (L3) autonomy marks the transition from supervised assistance to independent operation within strict boundaries. Think of L3 agents as junior developers working under a senior engineer’s strict guidelines.
An L3 agent doesn’t ask for permission for every step. It operates autonomously as long as predefined conditions are met. In software development, this usually means "run tests." If the agent writes code and all unit tests pass, it commits the change. If tests fail, it attempts to fix the code iteratively. Only if it gets stuck after several attempts does it escalate to the human.
The key enabler for L3 is comprehensive specification. You can’t give an L3 agent a vague prompt like "make this app faster." You need detailed acceptance criteria, robust test suites, and clear architectural constraints. The agent uses these as its source of truth. It behaves like a stateful system, maintaining context across sessions and monitoring its environment.
| Feature | Level 2 (Supervised) | Level 3 (Conditional) |
|---|---|---|
| Human Intervention | Frequent (per step/action) | Rare (only on failure/blocker) |
| Validation Mechanism | Human review of diffs | Automated tests/validation checks |
| Planning Horizon | Single task step | Multi-step workflow completion |
| Error Recovery | Ask user immediately | Retry/Debug loop before escalation |
| Trust Requirement | Low-Medium | High (requires solid test coverage) |
L3 is powerful because it decouples time from effort. You define the "what" and the "how it’s verified," and the agent handles the "how it’s built." This creates a productivity multiplier. Developers spend less time typing syntax and more time designing systems. However, if your test suite is weak, L3 becomes dangerous. Garbage in, garbage out-but now it’s automated garbage out.
Level 4: High Autonomy with Minimal Intervention
Welcome to the frontier. Level 4 (L4) autonomy represents agents that handle most routine decisions independently. These systems don’t just follow specs; they understand intent. They can choose between multiple valid implementation strategies based on performance metrics, maintainability, or cost, without asking you which one you prefer.
At L4, the human role shifts dramatically. You are no longer reviewing every pull request. Instead, you monitor dashboards, review exceptions, and provide strategic direction. The agent pre-selects options and seeks confirmation only for high-risk deviations. For instance, an L4 agent might decide to rewrite a legacy component using a new framework because it predicts better long-term maintenance costs, even if you didn’t explicitly ask for a rewrite.
L4 agents excel in environments with high volumes of lower-stakes decisions. Imagine managing microservices where dozens of small updates happen daily. An L4 agent can triage alerts, apply patches, update documentation, and deploy changes, flagging only anomalies for human review. This scales operations significantly.
But L4 comes with a caveat: opacity. Because the agent makes many implicit decisions, understanding *why* something happened can be harder. Effective L4 systems must include explainability features, logging the rationale behind major choices. Without this, debugging becomes a nightmare.
Beyond L4: The Concept of L5
Some frameworks extend to Level 5, representing fully autonomous agents requiring no human involvement. These systems operate over long time horizons, planning months ahead, adapting to market changes, and modifying their own goals. While theoretically possible, true L5 remains rare in practical enterprise applications today due to liability and alignment concerns. Most current "autonomous" products claim L3 or early L4 capabilities.
How to Move Up the Autonomy Ladder
You can’t just flip a switch to go from L1 to L4. Moving up requires infrastructure changes. Here is a roadmap:
- From L1 to L2: Implement basic tool use. Allow the agent to read files and execute simple commands. Introduce a "confirm before executing" layer.
- From L2 to L3: Invest heavily in testing. Your test suite must be reliable enough to serve as the gatekeeper for autonomous actions. Define clear success criteria for tasks.
- From L3 to L4: Build observability. You need logs that explain agent decisions. Create feedback loops where the agent learns from past corrections. Establish guardrails for risky actions (e.g., database deletions).
Start small. Pick a repetitive, well-defined task-like generating API documentation from code comments-and try automating it at L3. Once you trust the output, expand the scope.
Common Pitfalls and Risks
One major trap is "automation bias," where users blindly trust higher-level agents. Just because an agent acts autonomously doesn’t mean it’s correct. Another issue is the "brittle boundary" problem. An agent might be perfectly autonomous within a specific module but fail catastrophically when interacting with external APIs that change unexpectedly.
Security is also paramount. Higher autonomy means larger attack surfaces. An L4 agent with write access to your production database can cause massive damage if manipulated by prompt injection attacks. Always restrict permissions to the minimum necessary for the assigned level of autonomy.
Final Thoughts on Choosing Your Level
There is no single "best" level of autonomy. It depends on the task’s complexity, the cost of errors, and the maturity of your infrastructure. For creative brainstorming, L1 is perfect. For refactoring legacy code with good tests, L3 shines. For scaling DevOps pipelines, L4 offers the best ROI.
The future isn’t about replacing humans with robots; it’s about shifting human focus from execution to definition. As agents climb the autonomy ladder, our job becomes clearer: specify the desired outcome accurately, verify the results rigorously, and guide the strategy wisely.
What is the main difference between L2 and L3 agents?
The primary difference is the validation mechanism. L2 agents require human approval for each step or major action. L3 agents operate autonomously within defined boundaries, relying on automated tests or validation criteria to confirm success before proceeding, only escalating to humans if those checks fail.
Can I use an L4 agent for creative writing?
Generally, no. L4 autonomy relies on objective success criteria (like passing tests). Creative writing lacks objective metrics for "correctness," making it difficult for an agent to self-validate without human feedback. L1 or L2 is typically better suited for creative tasks.
Why is testing so important for L3 autonomy?
In L3 systems, the agent decides when a task is complete. If there are no automated tests to verify functionality, the agent has no way to know if its solution works. Tests act as the "ground truth" that allows the agent to iterate and self-correct without human intervention.
Are L4 agents completely unsupervised?
No. L4 agents operate with minimal intervention, but they still require supervision. Humans monitor overall performance, handle exceptions that fall outside defined parameters, and set strategic goals. True unsupervised operation (L5) is largely theoretical in current commercial applications.
How does prompt engineering relate to autonomy levels?
Prompt engineering evolves with autonomy. At L1, prompts are direct instructions. At L3 and L4, prompts become specifications and constraints. You describe the desired outcome and the rules, allowing the agent to determine the steps. Clear, structured prompts are essential for higher autonomy levels to prevent ambiguity.