You just built a chatbot for your customer service team. It works great until someone asks it to summarize a contract, and the model accidentally spits out a previous customer's Social Security number or starts rambling about inappropriate topics. This isn't a bug in the code; it's a feature of how Large Language Models (LLMs) work. They predict the next word based on probability, not truth or policy. That's why output filtering is non-negotiable for any production-grade AI application.
Think of output filtering as the bouncer at the door of a club. The model generates the response (the guest), but the filter decides whether that guest gets to enter the conversation with the user. Without it, you're exposing your brand to legal risks, privacy violations, and reputational damage. But here's the catch: if the bouncer is too strict, legitimate users get turned away. If they're too loose, troublemakers walk right in. Finding that balance is the core challenge of modern AI security.
Why Input Filtering Isn't Enough
Many developers assume that if they sanitize the input, the output will be safe. That's a dangerous misconception. Even with clean inputs, models can hallucinate facts, leak training data, or drift into unexpected territories due to their stochastic nature. A user might ask a benign question like "Tell me about recent healthcare costs," and the model could respond with a fabricated statistic that sounds plausible but is entirely wrong, or worse, include a snippet of private health data from its training set.
Input filtering stops malicious prompts before they reach the model. Output filtering catches what the model actually says. These are two different problems requiring two different solutions. For instance, a prompt injection attack might sneak past input filters by using encoded characters, resulting in an output that contains executable code or sensitive system instructions. You need to scan the final text string before it hits the user's screen.
The Three Layers of Defense
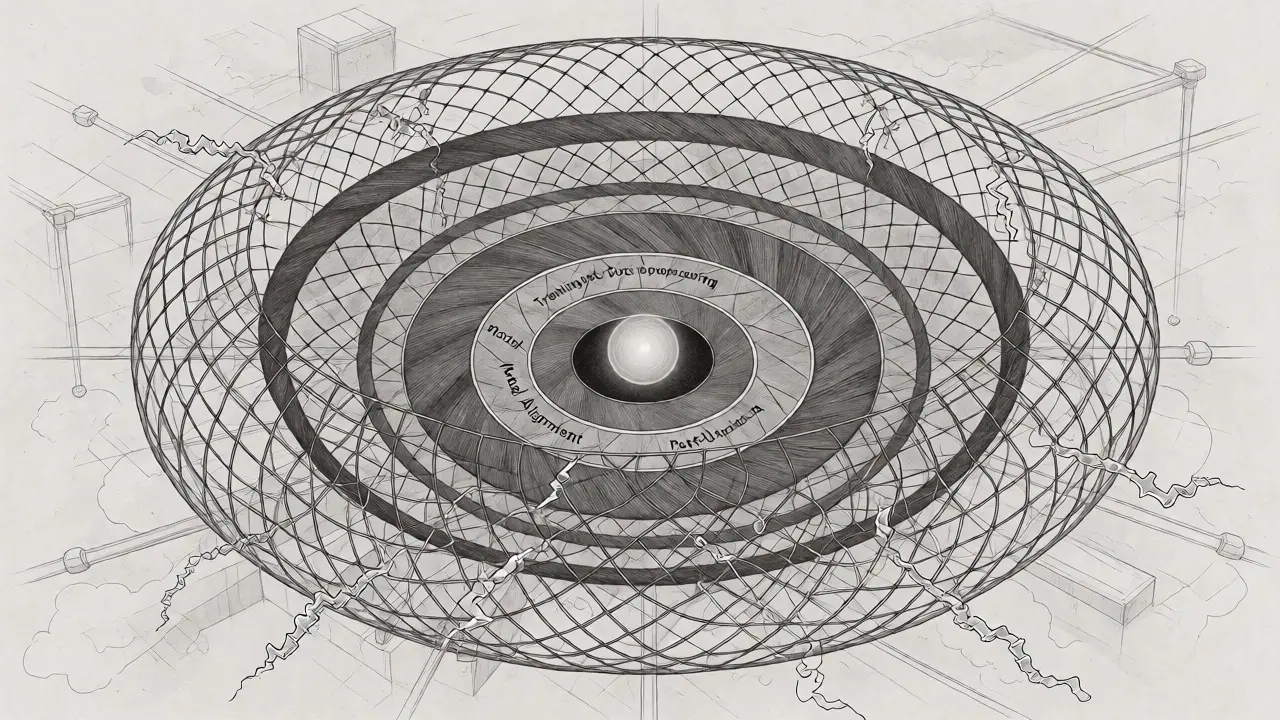
According to industry standards from IBM and other leaders, effective AI safety infrastructure operates across three distinct phases. Understanding where your filtering happens helps you choose the right tools.
- Training Data Preprocessing: This happens before the model even exists. Engineers scrub datasets to remove toxic language or personal information. While crucial, this doesn't guarantee the trained model won't generate new combinations of words that are problematic.
- Model Alignment: During fine-tuning, techniques like Reinforcement Learning from Human Feedback (RLHF) teach the model to prefer helpful and harmless responses. This shapes behavior but doesn't provide hard guarantees against edge cases.
- Post-Deployment Control: This is where real-time output filtering lives. It scores and screens generated text without needing to retrain the model. This layer is flexible, allowing you to update rules instantly when new threats emerge, such as a new type of jailbreak or a change in compliance regulations.
Most organizations rely heavily on post-deployment control because it offers the agility needed in fast-moving environments. You don't want to wait weeks for a model retraining cycle to block a newly discovered offensive phrase.
Practical Tools and Frameworks
You don't have to build these systems from scratch. Several robust solutions exist, each with its own strengths depending on your infrastructure and risk tolerance.
| Solution | Primary Mechanism | Best Use Case | Key Feature |
|---|---|---|---|
| OpenAI Moderation API | Classification-based scanning | General-purpose chatbots | Simple flagging for hate, sexual, violence, and self-harm categories. |
| Amazon Bedrock Guardrails | Categorized detection + PII masking | AWS-native enterprise apps | Detects PII (SSNs, dates) and supports custom regex patterns. |
| Cloudflare Firewall for AI | Edge-level network filtering | Multi-model deployments | Blocks topics at the network boundary without changing app code. |
| IBM HAP/MUTED | Linguistic span analysis | Nuanced sentiment analysis | Identifies specific offensive spans within sentences, not just whole strings. |
Let's look closer at Amazon Bedrock Guardrails. It’s particularly strong for enterprises dealing with regulated data. It doesn't just check for bad words; it uses probabilistic methods to detect Personally Identifiable Information (PII) like Social Security numbers or addresses. If the model leaks a date of birth, Bedrock can redact it automatically. It also handles complex scenarios like detecting harmful content inside code comments or variable names, which is vital if your LLM writes software.
On the other hand, Cloudflare's approach is fascinating for scale. By placing the filter at the edge, it applies consistent rules across all models you use-whether you're switching between GPT-4, Claude, or Llama. You define a guardrail once, say "block political discussions," and Cloudflare enforces it regardless of which backend model processes the request. This centralization saves massive amounts of engineering time.
The False Positive Dilemma
Here is the trade-off every CTO faces: strictness versus usability. If you set your filters to catch everything remotely suspicious, you'll start blocking valid content. Imagine a medical chatbot refusing to answer questions about "breast cancer" because a naive keyword filter flags the word "breast" as sexual content. That's a false positive, and it frustrates users who lose trust in the system.
Conversely, lenient settings let harmful content slip through. A subtle insult might not trigger a basic keyword list. Advanced systems use contextual understanding to solve this. For example, IBM's MUTED tool breaks down sentences to identify the target entity and the offensive span separately. In the sentence "Those politicians are incompetent," it identifies "politicians" as the target and "incompetent" as the negative attribute. It then assesses the intensity. This granularity allows for smarter decisions than simple blacklists.
To mitigate false positives, consider a tiered response strategy. Instead of blocking the entire message, replace the flagged segment with a generic placeholder like "[redacted]" or append a disclaimer. Or, route low-confidence flags to a human reviewer queue while high-confidence blocks happen automatically.
Advanced Techniques: Encoding and Jailbreaks
Hackers are getting creative. They don't just type insults; they encode them. Research published on arXiv highlights the importance of detecting base64, hexadecimal, and URL-encoded content. A user might send a string like "VGhlIG1vZGVsIGlzIGJyb2tlbg==" instead of "The model is broken." Simple text filters miss this. Your output filter needs to decode and analyze these patterns before deciding if the result is safe.
Another sophisticated threat involves adversarial perturbation, where slight changes to input cause the model to output nonsensical or harmful text. Some frameworks combine zero-shot classification with keyword analysis to achieve detection rates over 98%. These systems also leverage "adversarial research literature" as context, teaching the filter what common jailbreak attempts look like. This proactive stance is far more effective than reactive rule updates.
Implementation Checklist
If you're deploying an LLM today, run through this checklist to ensure your output handling meets OWASP Gen AI Security Project standards for insecure output handling:
- Define Categories: What counts as harmful? Hate speech? Violence? Leaked PII? Hallucinations? Be specific.
- Choose Your Layer: Will you filter in the application code, via an API call, or at the network edge?
- Test for Encodings: Ensure your filter decodes Base64 and URL encodings before scanning.
- Set Thresholds: Determine confidence scores for blocking vs. warning. Don't aim for 100% recall if it kills precision.
- Log Everything: Keep records of filtered outputs. This data is gold for tuning your filters and proving compliance during audits.
- Plan for Latency: Filtering adds milliseconds to response time. Optimize for speed, especially in real-time chat interfaces.
The Future of Output Safety
We are moving toward tighter integration. Currently, filters are often bolted on after the model speaks. Future architectures may embed safety mechanisms directly into the generation process, making the model itself more aware of constraints. However, external filters will remain critical for multi-vendor environments and rapid policy changes.
As models become more multilingual, your filters must keep up. An English-centric filter will fail spectacularly on Spanish or Japanese outputs. Look for solutions that offer native multilingual support rather than relying on translation layers, which introduce additional points of failure.
What is the difference between input and output filtering?
Input filtering scans the user's prompt to prevent malicious instructions or sensitive data from entering the model. Output filtering scans the model's generated response to ensure it is safe, relevant, and free of leaked information before being shown to the user. Both are necessary for comprehensive security.
Can output filtering stop hallucinations?
Not directly. Standard output filters detect toxicity, PII, and policy violations. They do not verify factual accuracy. To catch hallucinations, you need separate validation layers, such as retrieval-augmented generation (RAG) checks or fact-checking modules that compare the output against trusted sources.
How does Amazon Bedrock Guardrails handle PII?
Bedrock Guardrails uses probabilistic detection methods to identify personally identifiable information like social security numbers, dates of birth, and addresses. It can automatically mask or redact this data in the output stream, ensuring compliance with privacy regulations like GDPR or HIPAA.
Is Cloudflare's AI Firewall compatible with all LLMs?
Yes, because it operates at the network edge. It inspects HTTP traffic flowing between your application and any LLM provider. This means you can apply consistent safety policies across multiple models (e.g., OpenAI, Anthropic, Meta) without modifying your application code for each one.
What are the risks of overly aggressive output filtering?
Aggressive filtering leads to high false positive rates, where legitimate content is blocked or altered. This degrades user experience and can make the AI seem unreliable or overly cautious. Users may abandon the service if their valid queries are consistently rejected.

