You ask a chatbot for a legal precedent, and it confidently cites a case that never happened. You ask for a medical dosage, and it invents a drug interaction. This is the hallucination problem in Large Language Models (LLMs): when an AI generates information that looks plausible but is factually wrong. It’s not just a glitch; it’s a fundamental barrier to trusting AI in business. A January 2024 study found that 78% of AI practitioners list hallucinations as their top concern for production deployment. If you’re building or deploying LLMs, fixing this isn’t optional-it’s survival.
Why Do LLMs Make Things Up?
To fix hallucinations, you have to understand why they happen. LLMs aren’t databases; they are probabilistic engines predicting the next likely word. They don’t "know" facts; they recognize patterns. When the pattern matching goes slightly off, or when the model tries to fill a gap in its training data with something that sounds right, it fabricates an answer. The 2022 Microsoft Research paper by Ji et al. first systematically mapped this out, showing that errors stem from issues in factual accuracy, logical consistency, and instruction following.
The stakes are high. In enterprise settings, a hallucinated number in a financial report or a fake citation in a legal brief can lead to compliance violations and lost trust. Unlike a human who might say "I don't know," an LLM often defaults to confident fabrication. That confidence is the dangerous part. It makes the error hard to spot unless you have specific controls in place.
Tweak Your Inputs: Prompt Engineering Tactics
Before you retrain models or build complex infrastructure, look at your prompts. Small changes here yield big results. Temperature control is the easiest lever. High temperature (0.8-1.0) encourages creativity but increases randomness. Dropping it to the 0.2-0.5 range makes outputs more deterministic, reducing hallucinations by up to 45% according to McGovern Institute guidelines.
Then there’s structure. Microsoft’s Azure AI team recommends the "ICE method": Instructions, Constraints, Escalation. Place critical constraints at the very start of your prompt. Repeat key instructions two or three times. Most importantly, give the model permission to fail. Explicitly telling it to "Say 'I don't know' if unsure" reduces hallucinations by 37% in testing. Why? Because it removes the pressure to always produce an answer. Chain-of-thought prompting, where you ask the model to reason step-by-step before answering, cuts errors by another 28%. It forces the model to check its own logic before committing to a final statement.
Ground Your Answers: Retrieval-Augmented Generation (RAG)
If prompt engineering is a band-aid, Retrieval-Augmented Generation (RAG) is the surgery. RAG works by fetching relevant documents from your own database before the LLM generates a response. Instead of relying solely on what the model memorized during training, it grounds its answer in real, verifiable data. AWS research shows this approach reduces hallucination rates by 63-72% across various benchmarks.
But RAG isn’t plug-and-play. Garbage in, garbage out. If your source documents are messy, outdated, or poorly organized, RAG can actually make things worse. IBM found that uncurated data increased hallucination rates by 22% in some cases. Successful implementation requires cleaning your data, organizing it into topic-specific collections, and auditing it regularly. Tools like RAGAS (Retrieval Augmented Generation Automatic Score) help measure success, correlating closely with human evaluation to tell you if your answers are actually correct.
Teach the Model: Fine-Tuning vs. Knowledge Injection
Sometimes, you need the model itself to know more. Fine-tuning involves training the model on specific domain data, like medical records or legal contracts. For specialized tasks, this is powerful. Microsoft testing showed that domain-specific fine-tuning reduced hallucinations by 58% in medical applications compared to general-purpose models.
However, fine-tuning is expensive. Creating a high-quality dataset often takes 200-300 hours of expert annotation. For smaller teams, this might be overkill. An alternative is Knowledge Injection (KI), which embeds specific facts into smaller models (like 7B parameter ones) without full retraining. This achieved a 43% reduction in hallucinations while keeping inference speed fast. If you have limited resources, start with KI or RAG. Save heavy fine-tuning for when you have massive, clean datasets and strict regulatory needs.
Catch Errors Early: Post-Generation Verification
Even with good prompts and RAG, mistakes slip through. That’s where post-generation checks come in. Decoding strategies like Contrastive Decoding (CAD) adjust how the model selects words, reducing hallucinations by nearly 30%. More advanced methods use Natural Language Inference (NLI) frameworks to check if the generated sentence logically follows from the source text. These systems can detect 82% of hallucinations accurately.
For critical applications, consider human-in-the-loop systems. Amazon Bedrock Agents, for example, can trigger alerts when a response’s confidence score drops below a threshold. This allows human experts to review potentially flawed answers before they reach the customer. While this adds latency-up to 600ms-it dramatically improves reliability. In healthcare and finance, that trade-off is usually worth it.
Choosing Your Strategy: A Decision Framework
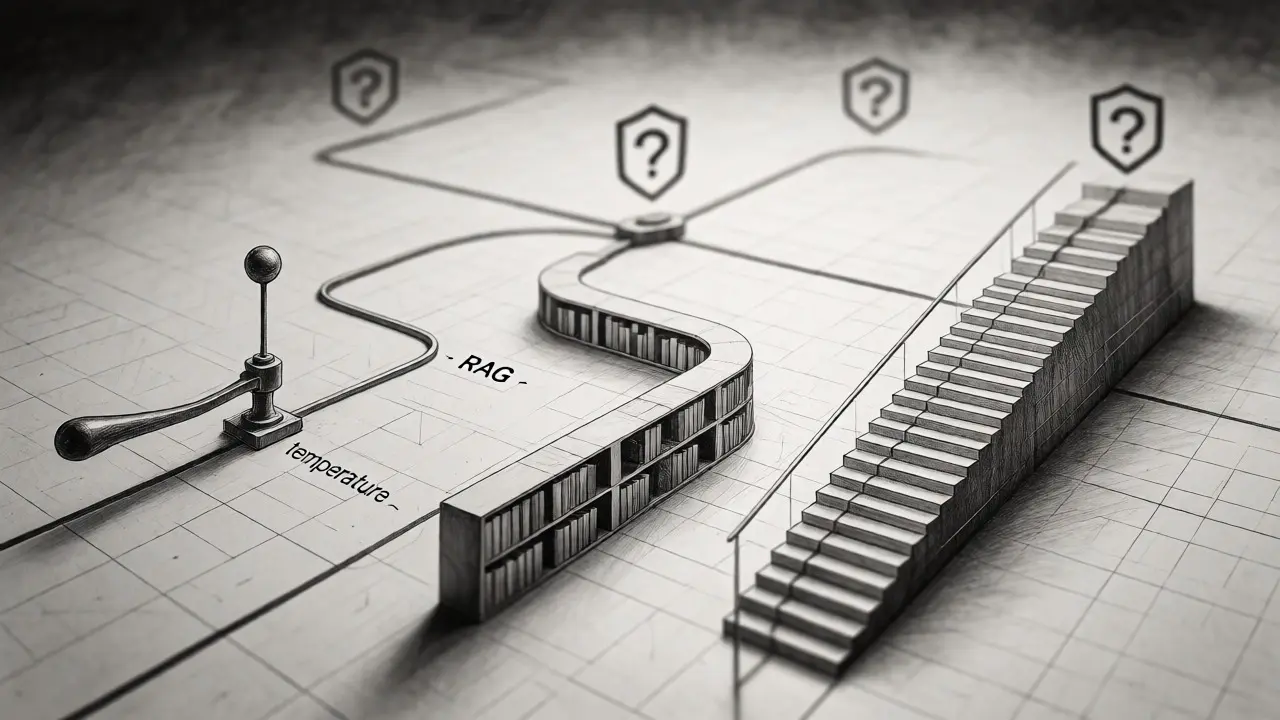
Not every project needs every solution. Here’s how to pick based on your constraints:
| Technique | Hallucination Reduction | Resource Cost | Best For |
|---|---|---|---|
| Prompt Engineering | 18-45% | Low | Quick fixes, low-budget projects |
| RAG | 63-72% | Medium | Fact-heavy queries, dynamic data |
| Fine-Tuning | ~58% | High | Specialized domains (medical/legal) |
| Post-Verification | 29-41% | Medium-High | Critical accuracy requirements |
Most successful enterprises combine these. Gartner reports that 68% of Fortune 500 companies use at least one mitigation technique, with RAG being the most popular (52%). Healthcare firms lean heavily on RAG plus knowledge injection due to regulations, while financial services prefer human-in-the-loop checks for compliance.
What’s Next for Factuality Control?
The field is moving fast. Anthropic’s constitutional AI approaches, which bake factuality rules into the model’s architecture, show promise with 73% reduction in early tests. Multimodal verification-checking text against images or structured data-is also gaining traction. By 2027, analysts predict enterprise hallucination rates could drop to 8-12%. But Stanford HAI warns that as models get better at complex reasoning, new types of subtle errors will emerge. There is no silver bullet. Reducing hallucinations is an ongoing process of monitoring, adjusting, and verifying.
Frequently Asked Questions
Can I eliminate hallucinations completely?
No. Current technology reduces hallucinations significantly but cannot eliminate them entirely. As models become more creative and capable of complex reasoning, new forms of subtle inaccuracies may appear. The goal is risk management, not perfection.
Is RAG always better than fine-tuning?
Not always. RAG is better for accessing up-to-date or vast external information. Fine-tuning is better for teaching the model a specific style, tone, or deep domain expertise that doesn't change frequently. Many systems use both.
How does temperature affect hallucinations?
Lower temperatures (0.2-0.5) make the model more deterministic and conservative, sticking closer to probable tokens. Higher temperatures (0.8+) encourage diversity but increase the chance of selecting less probable, potentially incorrect tokens, leading to more hallucinations.
Do larger models hallucinate less?
Generally, yes. Larger models have more parameters and training data, which helps them distinguish between fact and fiction better. However, size alone isn't enough; without grounding techniques like RAG, even large models can still fabricate details confidently.
What is the cost of implementing RAG?
Costs vary based on data volume and infrastructure. You need storage for vector databases, compute power for embeddings, and maintenance time for data cleaning. While cheaper than fine-tuning, poor data quality can negate benefits, so budget for data curation.