You look at a spec sheet for an AI model and see "70 billion parameters." You assume that means it's smarter than the 7-billion-parameter model sitting next to it. For years, this was the only metric that mattered in the Large Language Model (LLM) industry. Bigger meant better. More parameters meant more knowledge. But if you've tried to build a reliable reasoning agent recently, you might have noticed something weird: sometimes a smaller, well-structured model outperforms a massive one on specific tasks, while other times, a huge model suddenly gains abilities that seem almost magical.
The truth is, calling a model "large" isn't just about counting numbers in a file. It’s about capability thresholds. Recent research from Stanford and other leading labs has shifted the conversation from raw size to architectural efficiency and emergent behaviors. We’re moving past the era where parameter count was the sole definition of scale. Today, we need to understand what actually makes a model "large" in terms of utility, reasoning depth, and real-world performance.
Key Takeaways
- Parameter count is no longer the whole story: While billions of parameters are still common, architectural innovations like Virtual Logical Depth (VLD) allow smaller models to achieve similar reasoning capabilities.
- Emergent abilities appear at specific thresholds: Capabilities like chain-of-thought reasoning often don't exist below certain sizes (e.g., ~62B parameters) but appear abruptly above them.
- Architecture matters as much as size: How weights are reused and how layers interact can decouple reasoning ability from raw parameter count.
- Cost vs. Capability trade-offs: Most enterprises find that mid-sized models (30B-70B) with optimized architectures offer the best balance, avoiding the diminishing returns of trillion-parameter models.
The Myth of Linear Scaling
For a long time, the logic was simple: add more data and more parameters, and the model gets linearly better. If doubling parameters gave you 10% better accuracy, quadrupling should give you 20%. But scaling laws aren't always smooth lines; they have cliffs and plateaus.
Consider BERT. When it launched in 2018, its 340 million parameters felt enormous. Today, that number looks quaint. Yet, BERT remains highly effective for many classification tasks. Why? Because "large" isn't a fixed number-it's a relative concept tied to the task. A model needs to be large enough to capture the complexity of the problem, but beyond a certain point, adding parameters yields diminishing returns unless the architecture supports deeper reasoning.
This disconnect became obvious when researchers started testing reasoning tasks. Google discovered in 2022 that chain-of-thought prompting-where you ask the model to show its work-only improved performance for models with at least 62 billion parameters. Below that threshold, asking a model to reason step-by-step actually made it worse. The model didn't have the internal capacity to follow the logical thread. This is an emergent ability: a skill that appears suddenly once a system crosses a critical complexity threshold.
Beyond Parameters: Introducing Virtual Logical Depth
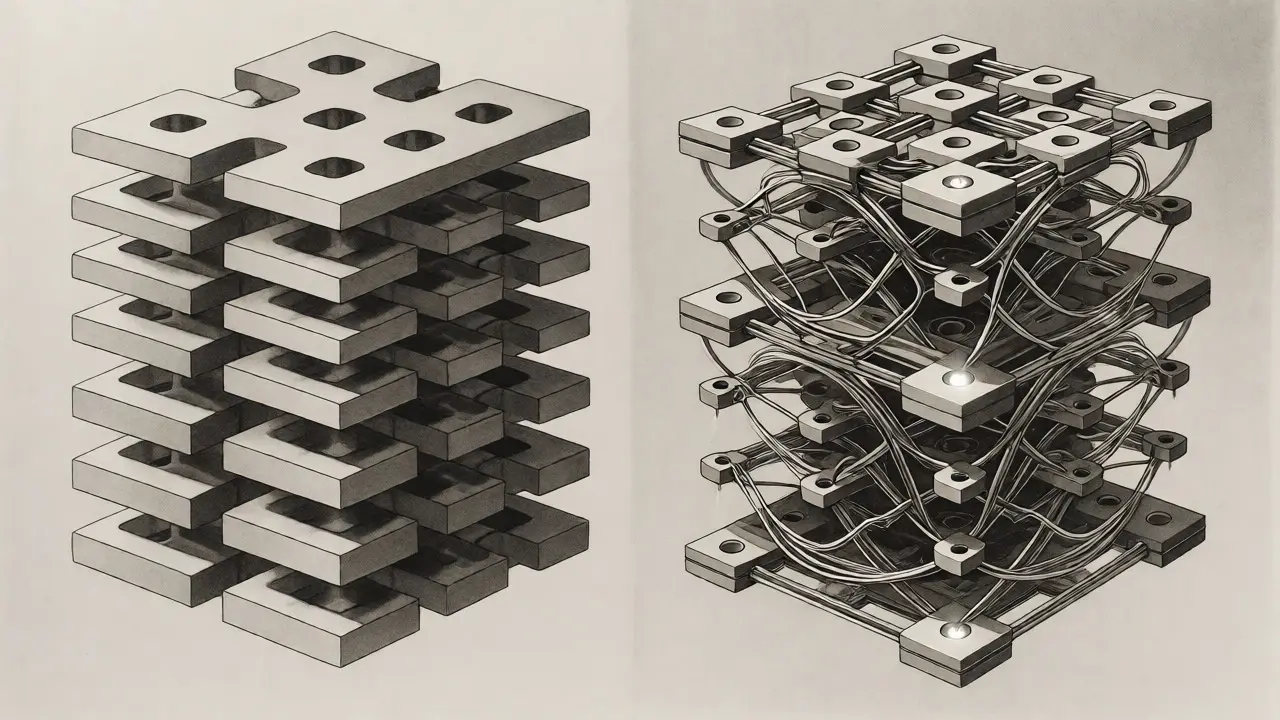
If parameter count doesn't tell the whole story, what does? Enter Virtual Logical Depth (VLD), a concept introduced by researchers at Stanford in mid-2025. VLD measures the effective algorithmic depth of a model without changing its parameter count. Think of it like reusing ingredients in a recipe. Instead of buying new spices for every dish, you reuse the same set in different combinations to create complex flavors.
In traditional models, each layer processes information once. In models using VLD, weights are strategically reused across layers during both training and inference. This increases the "logical depth"-the number of computational steps the model can take-without adding new parameters. The result? Reasoning capabilities improve significantly. Stanford’s experiments showed up to a 23.7% improvement on complex reasoning benchmarks using VLD, all while keeping the parameter count identical to the baseline model.
| Metric | Traditional Large Model | VLD-Enhanced Model |
|---|---|---|
| Parameter Count | High (e.g., 70B) | Identical to Baseline |
| Reasoning Accuracy | Baseline | +23.7% Improvement |
| Knowledge Capacity | Scales with Parameters | Nearly Unchanged |
| Compute Cost | Standard | Similar or Slightly Higher |
This distinction is crucial. VLD proves that reasoning ability can be decoupled from raw memory capacity. A model doesn't need to store every fact in the universe to think logically; it just needs to process information deeply enough. This challenges the industry's obsession with ever-larger parameter counts and suggests a new path forward: optimize how parameters are used, not just how many there are.
Emergent Capabilities: The Threshold Effect
So, when does a model become "large" in terms of capability? It happens when it crosses specific thresholds where new skills emerge. These aren't gradual improvements; they're jumps.
One clear example is multi-hop reasoning. Snorkel AI’s benchmarks show that models under 50 billion parameters achieve only about 42.3% accuracy on multi-hop tasks-questions that require connecting multiple pieces of information. But cross the 60-billion-parameter mark, and accuracy jumps to 78.9%. This isn't just a slight bump; it's a qualitative shift. Suddenly, the model can handle complex queries that previously required extensive prompt engineering or external tools.
Developers report this firsthand. One engineer noted that switching from an 8B model to a 70B model wasn't just about getting better answers-it fundamentally changed how the model approached problems. The larger model exhibited spontaneous chain-of-thought reasoning, whereas the smaller model needed explicit instructions to even attempt it. This autonomy-the ability to break down a problem without being told how-is a hallmark of truly "large" models.
Architecture and Knowledge Localization
Size also affects how knowledge is stored and retrieved within the model. Anthropic’s recent research highlights that larger models exhibit stronger "knowledge localization." In simpler terms, in bigger models, specific facts are stored in more distinct, isolated parts of the network. Smaller models tend to mix information, leading to "leakage" where unrelated concepts interfere with each other.
This has practical implications for reliability. If you ask a small model for a specific historical date, it might hallucinate because the relevant neurons are shared with too many other concepts. In a larger model, that fact has its own dedicated space, making retrieval more precise. This structural integrity is part of what makes a model feel "smarter," even if the underlying training data is similar.
Furthermore, architecture plays a role in perceived largeness. Bidirectional models like BERT process context differently than autoregressive models like GPT. BERT's design allows inputs and outputs to account for each other's context simultaneously, which can make a smaller bidirectional model outperform a larger unidirectional one on specific NLP tasks like sentiment analysis. So, "large" isn't just about volume; it's about the right structure for the job.
Practical Implications for Developers and Enterprises
If you're building applications today, do you need a trillion-parameter model? Probably not. Gartner’s 2026 enterprise survey found that 78% of companies standardized on models under 20 billion parameters. Why? Because cost constraints outweigh marginal capability gains for most use cases.
However, for complex reasoning tasks, the middle tier-models between 30B and 70B parameters with architectural optimizations like VLD-is becoming the sweet spot. These models offer the emergent reasoning capabilities of larger systems without the massive infrastructure costs. Deploying a 70B+ model typically requires high-end GPUs (like NVIDIA A100s with 80GB VRAM), costing around $12,500 per node monthly in cloud environments. For many businesses, that price tag is hard to justify when a 30B optimized model can handle 80% of commercial applications.
Here’s a quick decision framework:
- Under 10B Parameters: Best for specialized tasks, chatbots, and low-latency requirements. Cheap to run, but lacks deep reasoning.
- 10B-30B Parameters: Good general-purpose models. Suitable for summarization, translation, and basic Q&A.
- 30B-70B Parameters: The current "sweet spot" for reasoning. Offers emergent chain-of-thought capabilities at a manageable cost.
- 100B+ Parameters: Reserved for cutting-edge research, complex scientific discovery, or scenarios where maximum breadth of knowledge is non-negotiable.
The Future: Capability-Aware Scaling
The industry is shifting toward "capability-aware scaling." Instead of asking "How many parameters does this model have?", developers are asking "Can this model reason through this specific problem reliably?"
Stanford researchers argue that superintelligence might not require endless parameter growth. By increasing logical depth and optimizing weight reuse, we might reach higher levels of intelligence without exploding hardware requirements. This aligns with regulatory trends too. The EU AI Act now imposes stricter requirements on models above 50 billion parameters, recognizing their potential for autonomous reasoning. Compliance costs for these "large" models are estimated at $1.2 million per model, further incentivizing efficient, mid-sized architectures.
Ultimately, defining a model as "large" is no longer a static label. It's a dynamic assessment of its ability to handle complexity, reason autonomously, and maintain consistency. As we move forward, expect to see more models that are "small" in size but "large" in spirit, proving that intelligence isn't just about having the biggest brain, but about thinking the deepest thoughts.
Does a higher parameter count always mean better performance?
No. While larger models generally perform better on broad benchmarks, they suffer from diminishing returns. Architectural optimizations like Virtual Logical Depth can allow smaller models to match or exceed the reasoning capabilities of larger ones on specific tasks, often at a lower computational cost.
What is Virtual Logical Depth (VLD)?
VLD is a technique that increases a model's effective reasoning depth by reusing weights across layers during computation. This allows the model to perform more complex logical operations without increasing its total parameter count, effectively decoupling reasoning ability from model size.
Why do some capabilities only appear in very large models?
These are called "emergent abilities." They arise when a model crosses a specific complexity threshold (often around 60 billion parameters). Below this threshold, the model lacks the internal capacity to support skills like spontaneous chain-of-thought reasoning, even if explicitly prompted.
Is it worth deploying a 70B+ parameter model for my business?
It depends on your use case. If you need complex, multi-step reasoning, yes. However, for most standard tasks like summarization or customer service, models in the 10B-30B range offer a better cost-to-performance ratio. Always test against your specific data before committing to high-cost infrastructure.
How does knowledge localization affect model reliability?
Larger models tend to store facts in more isolated parts of the network, reducing interference between unrelated concepts. This leads to more accurate retrieval and fewer hallucinations compared to smaller models, where knowledge is more densely packed and prone to "leakage."